Raw capture — raw/freetoken.md
url: https://github.com/FlashML-org/FreeToken date_fetched: 2026-08-22
| Download | Paper | Developer Slack | Community Discord | Community WeChat |
Unlock datacenter-class intelligence on the hardware you already own — Run 290B+ frontier MoE models locally on your gaming PC at blistering interactive speeds.
FreeToken is an edge-native Mixture-of-Experts (MoE) serving engine designed for running frontier-scale open-weight models on personal and consumer hardware. It treats heterogeneous edge resources—GPUs, CPUs, host memory, and interconnects—as a unified, elastic inference platform. Its core features include:
Download FreeToken for Windows or Linux at flashml.ai. It sets the engine up for you and gives you a GUI for running models, chatting, and tuning the engine.
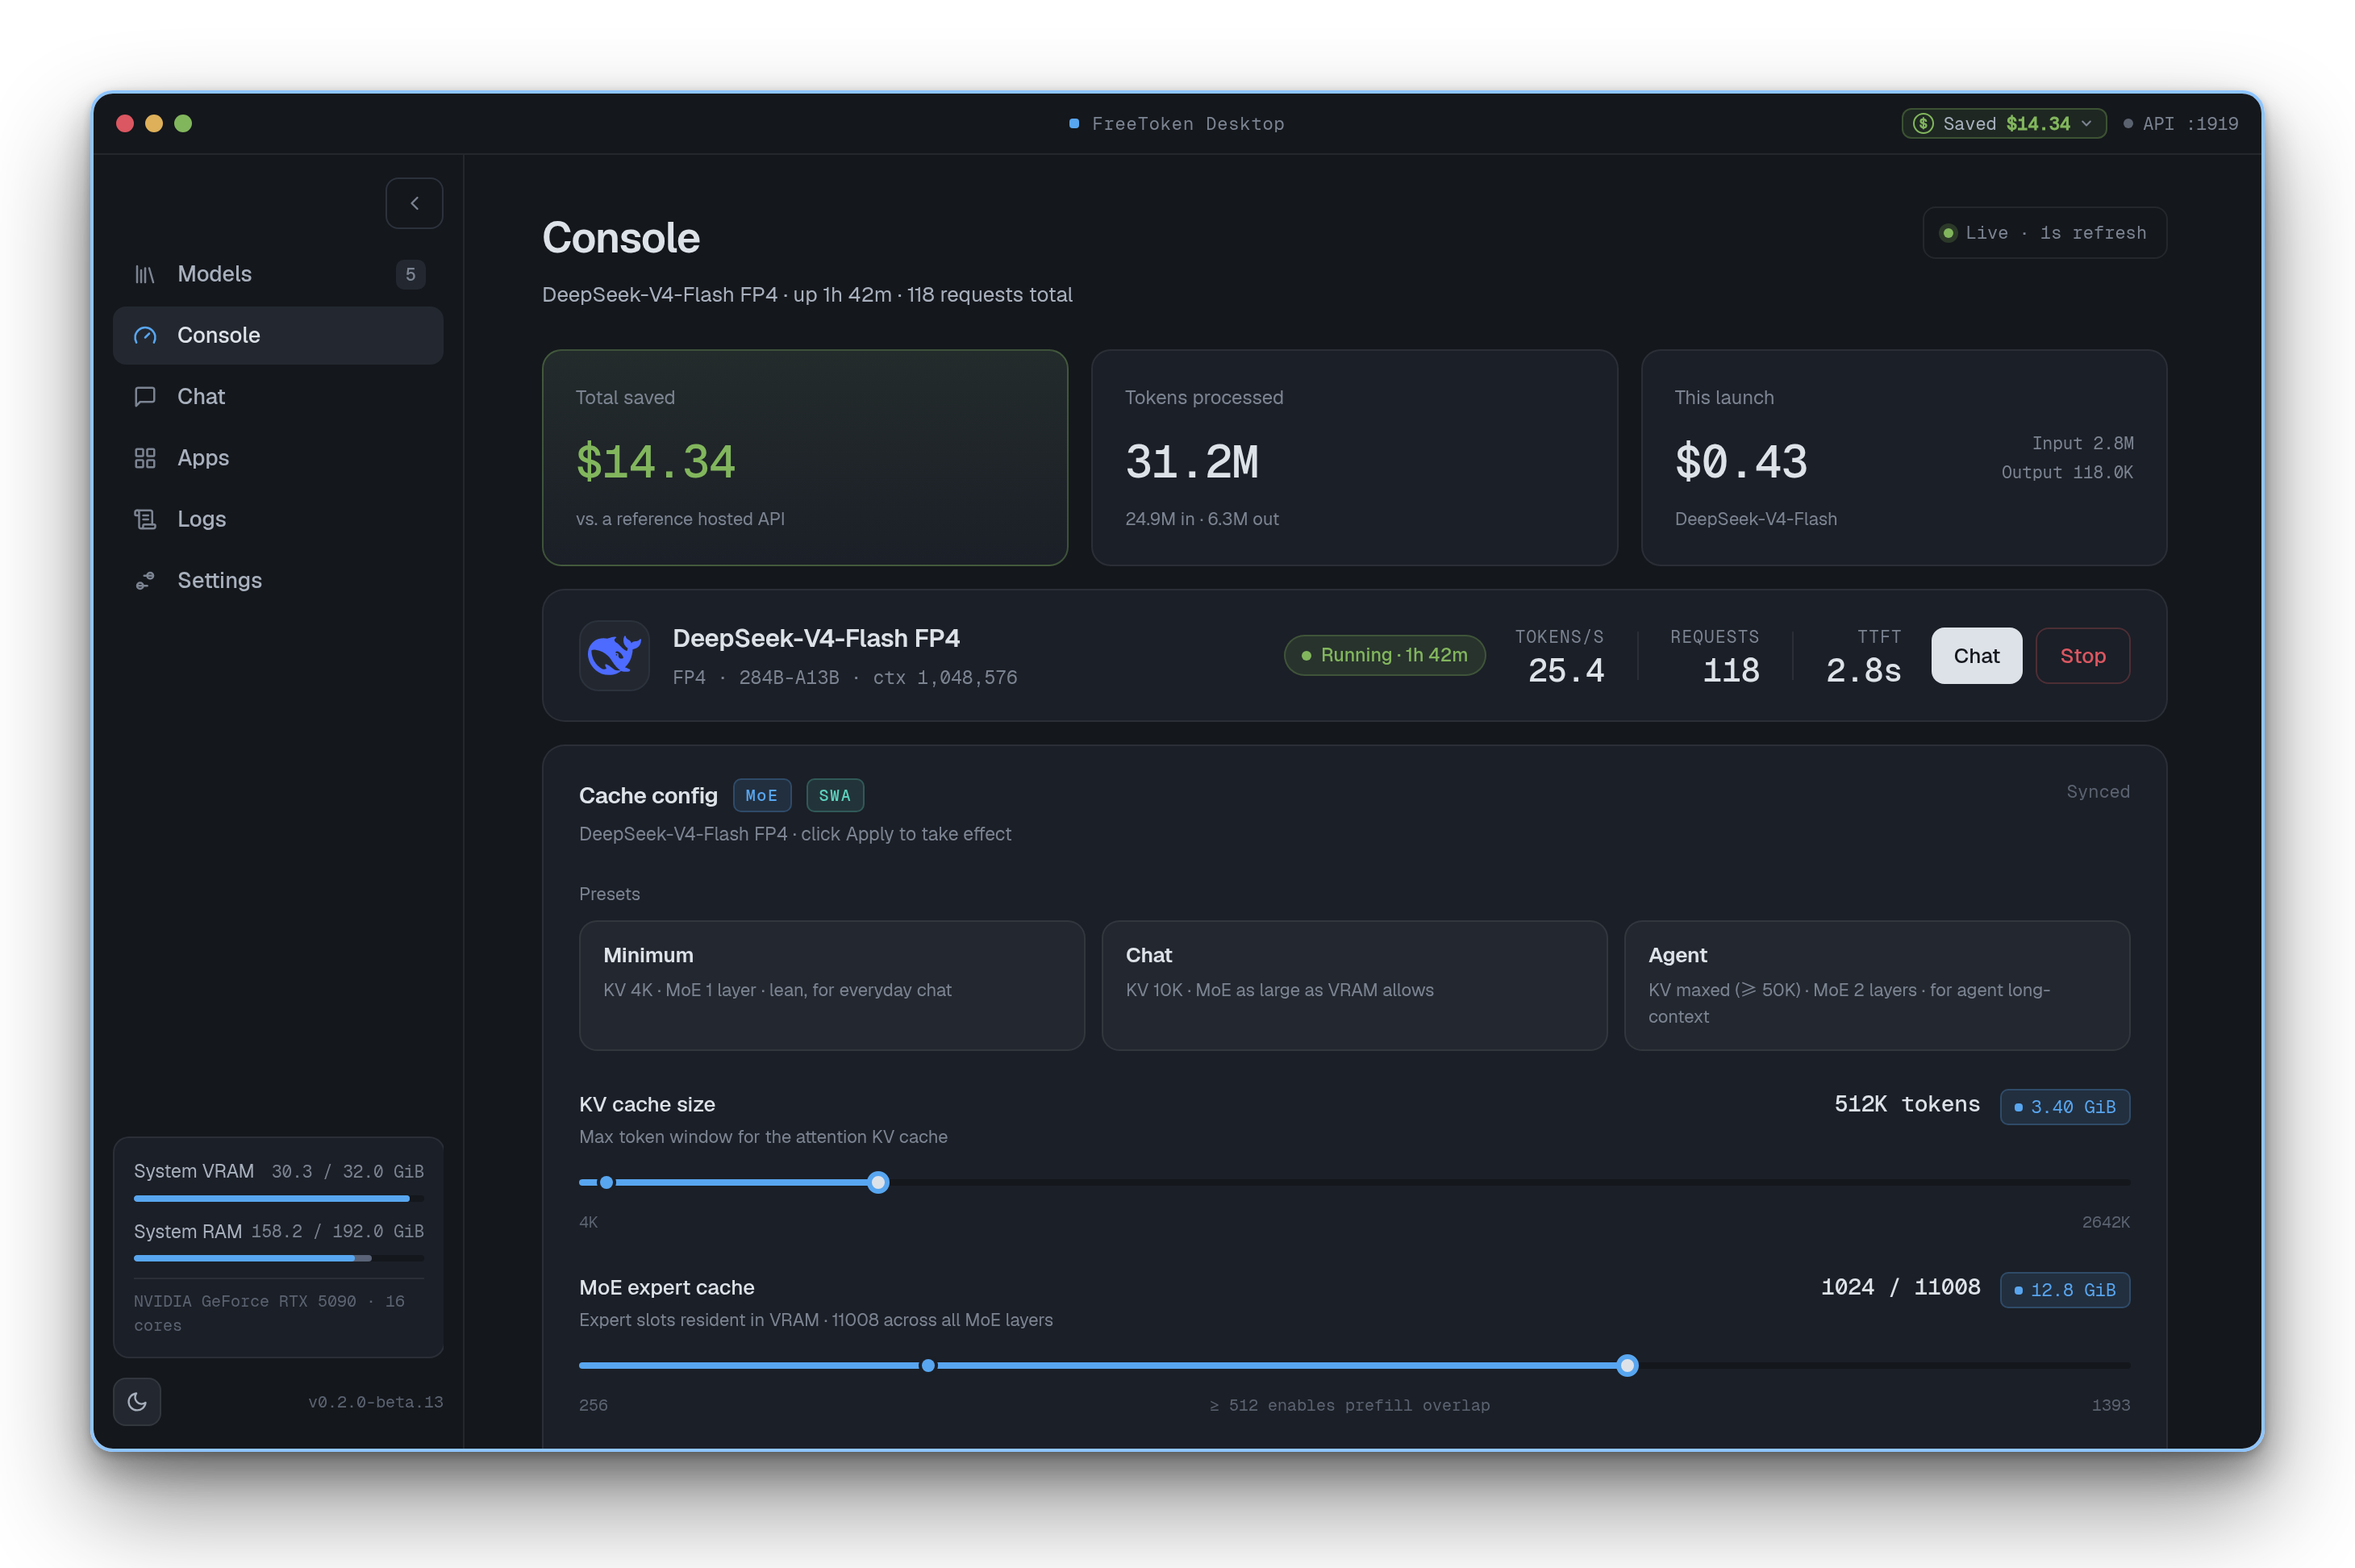
Install FreeToken with uv (recommended) or pip:
uv pip install "freetoken[accel]"
Or build from source:
git clone https://github.com/FlashML-org/FreeToken.git && cd FreeToken
uv venv && source .venv/bin/activate
uv pip install -e ".[accel]"
For More details:
If you use FreeToken for your research, please cite our paper:
@article{yang2026freetoken,
  title={FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution},
  author={Yang, Shuo and Fan, Xiaoze and Pan, Melissa and Xi, Haocheng and Wang, Zhe and Sun, Shanlin and Keutzer, Kurt and Han, Song and Zaharia, Matei and Xu, Chenfeng and Stoica, Ion},
  journal={arXiv preprint arXiv:2608.16157},
  year={2026}
}
FreeToken was deeply inspired by mini-sglang, and learned the design and reused code from the following projects: SGLang, vLLM, FlashInfer, flash-linear-attention, LightLLM and llama.cpp.
