Raw capture — raw/mlx-dspark.md
url: https://github.com/ARahim3/mlx-dspark date_fetched: 2026-08-21
DeepSeek's DSpark and z-lab's DFlash speculative decoding — native on Apple Silicon via MLX.
Lossless drafters (same output, just faster) for Gemma-4, Qwen3, Muse-Glimmer, Ornith-1.0, Qwen3.6, Qwen3.8, Nemotron, and Bonsai targets —
plus any matched DSpark / DFlash checkpoint. Run them at the CLI, from Python, serve an OpenAI-compatible API to LM Studio / any local tool,
or drive Claude Code with a model on your own Mac.



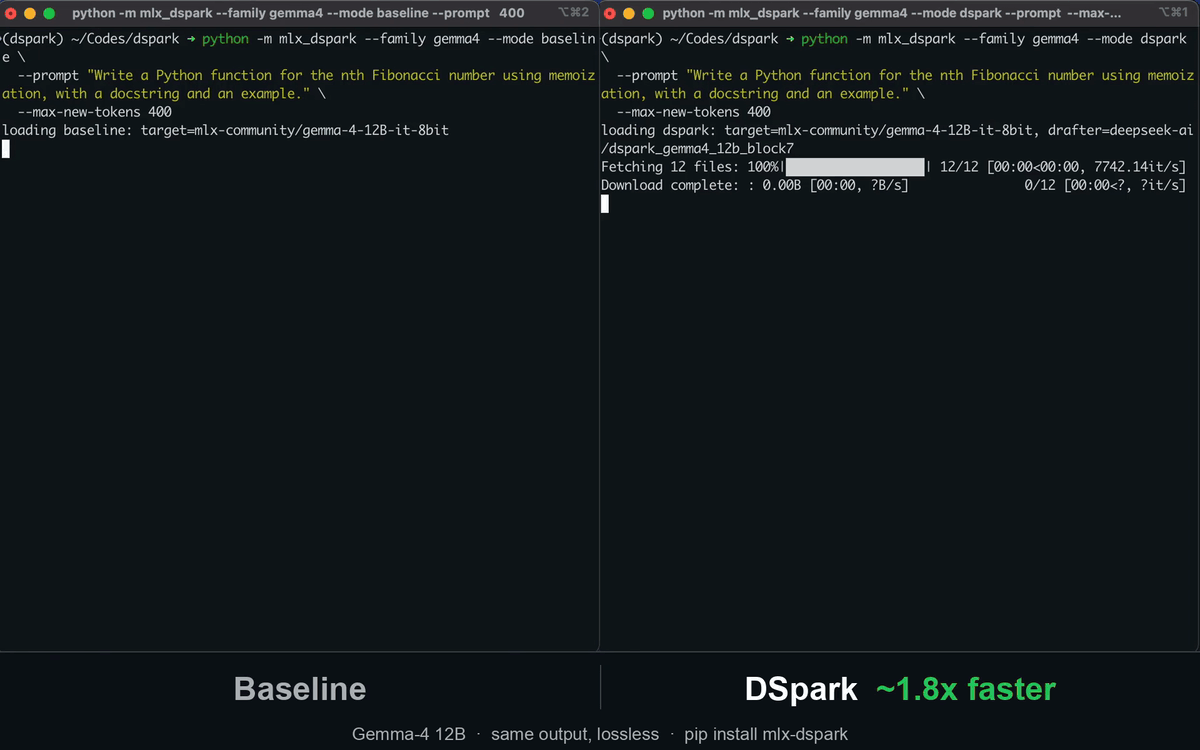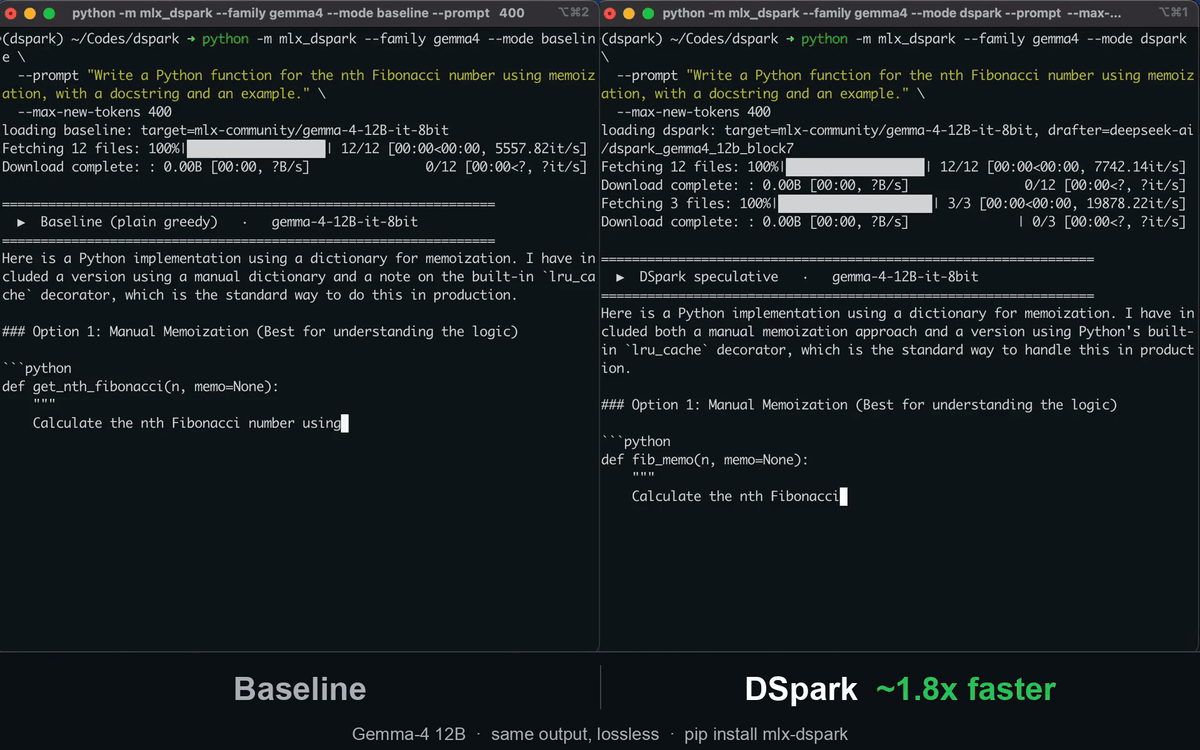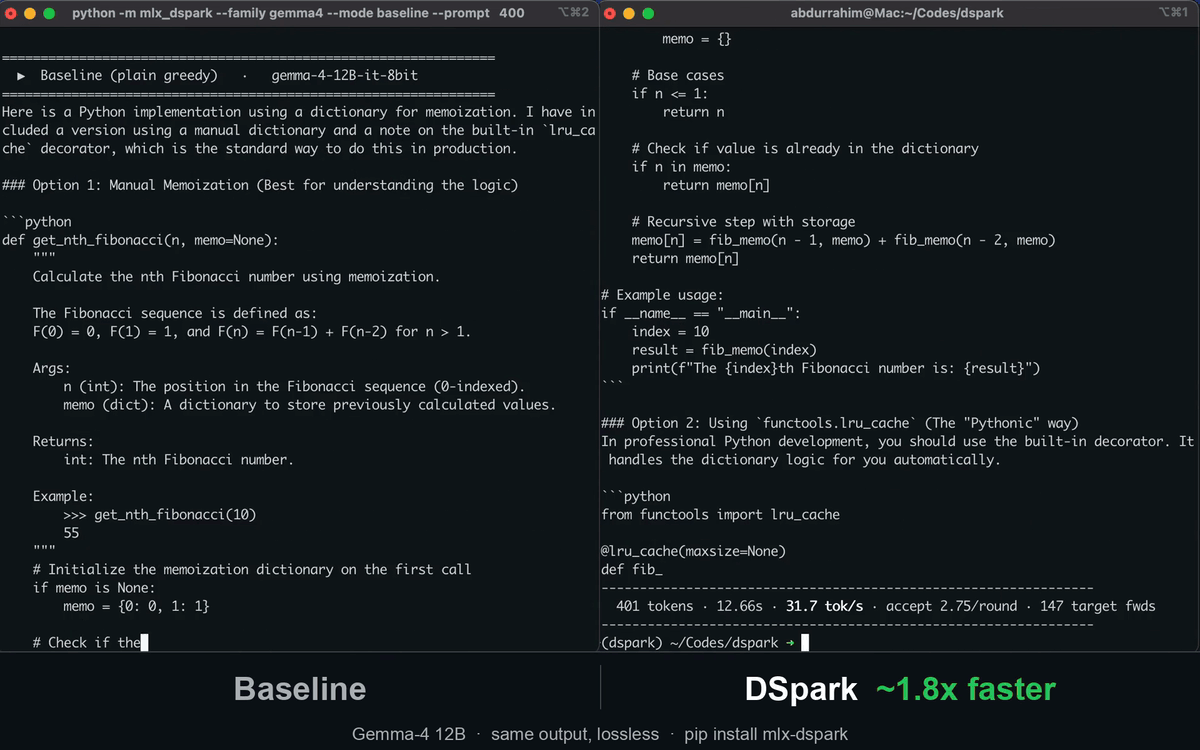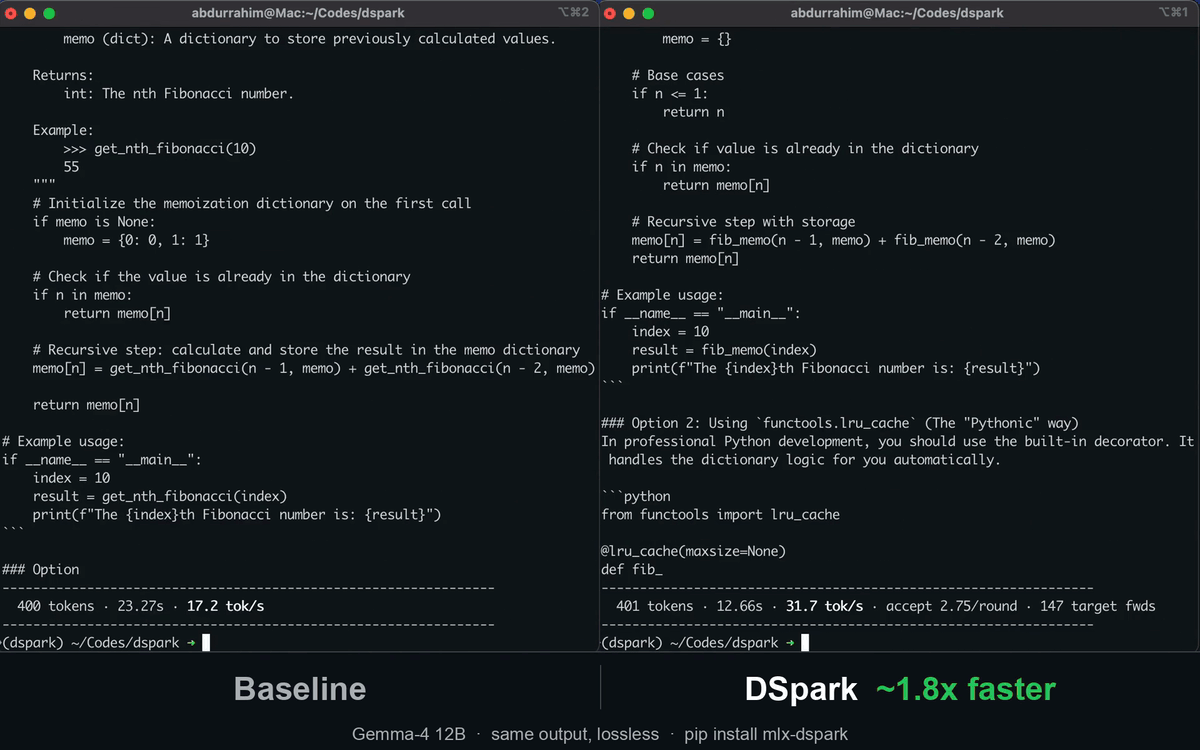
mlx-dspark runs two EAGLE-family speculative-decoding drafters natively on Apple Silicon: DeepSeek's DSpark (semi-autoregressive, from the DeepSpec codebase, used to accelerate DeepSeek-V4) and z-lab's DFlash (block diffusion). Both are lossless — the target verifies every token, so output is identical to normal decoding — and run under one verify loop, so you can serve them, script them, or benchmark them head-to-head.
What this is not: DeepSeek-V4 inference. The targets are consumer-size models (Gemma-4, Qwen3, Meta's Muse-Glimmer, NVIDIA's Nemotron, PrismML's ternary Bonsai-27B, …) with published DSpark drafters — so this runs the real drafter method on a Mac, but the model producing tokens is one of those, not V4. V4 Flash/Pro (MoE, batched serving) is DSpark's own headline use case.
Every row auto-resolves its drafter from --model (any quant of the target matches). Measured warm on
an M4 Pro, medians of 3 — most rows with mlx-dspark benchmark --trials 3 (three prompts:
chat/code/math), the Muse row per-content best (footnoted); full tables, baselines, and method in
Results at a glance. Sorted by best measured speedup:
[!TIP] Qwen3.8-27B's measured best is now a DFlash 2 drafter, on both quants —
incoai/Qwen3.8-27B-DFlash2(Inco AI's DFlash successor: a candidate path selector + dynamic convs that lift acceptance at the same verify width). Measured paired, same session, identical width 8: 8-bit 3.63× mean (4.06× math · 4.05× code · 2.79× chat, accept 5.53) vs the DSpark head's 2.92×; 4-bit 2.30× (accept 5.14, 33.8 tok/s — the fastest decode in this project) vs 2.01×. Chat gains the most (+40% at 8-bit). Greedy-lossless like everything here, and prefix caching covers this mode too. No flags needed:--mode auto— the default, and what the Mac app uses — resolves each row's measured-best mode, which is DFlash 2 here:```bash
the default mode (auto) resolves DFlash 2 for this target (downloads it once):
mlx-dspark serve --model mlx-community/Qwen3.8-27B-8bit mlx-dspark generate --model mlx-community/Qwen3.8-27B-8bit --prompt "…"
name a mode explicitly to A/B; --mode dspark still gets the DSpark heads:
mlx-dspark generate --model mlx-community/Qwen3.8-27B-4bit --mode dspark --prompt "…" ```
No cap flag needed: the dflash default (full block = cap 7) is the measured optimum on both quants. The DSpark rows remain the measured best of their mode —
DimInfer/Qwen3.8-27B-Dspark-v1at 4-bit (1.99–2.01×, cap 7, no confidence flag) andRadixArk/Qwen3.8-27B-DSparkat 8-bit (2.72–2.92×, cap 7) — see DSpark vs DFlash for the head-to-head.
The speed column is the measured range across the three benchmark contents at the row's best configuration — chat at the low end, code/math at the high end (decoding speed depends on what is being generated: copy- and structure-heavy content accepts longer drafts). Baselines and per-content splits are in Results at a glance.
This table is the set of pairs we have measured and vouch for, which is also exactly the
auto-resolve registry — that is the only thing the registry is for. It is not the set of models
that work: any DeepSpec-native drafter runs against any compatible target via --drafter, and any
target at all gets drafter-free speculation via --mode auto. See
Bring your own drafter. Per-model caveats and
methodology live in the numbered footnotes at the end of this page — click a marker to jump.
Target precision: the quants shown are each model's measured best — ratios are non-monotone in bits and peak at 8-bit on current MLX (full Ornith sweep: 4-bit 1.38× · 8-bit 2.17× · bf16 1.54× on code; bf16 loses in both ratio and absolute speed because MLX's unquantized matmul pays a ~2× cost cliff at verify width 2). Details in Results at a glance.
Nothing in this table is hand-tuned per model, and none of it is pinned to this M4 Pro:
with no --max-draft, mlx-dspark measures your machine's verify/drafter cost curves once
(~5 s, cached per model + quant + mlx version) and derives the draft cap from them — an M1 or
an M5 gets its own optimum, not the one these rows were measured at. --max-draft auto
additionally adapts the cap per round while generating. See Tuning.
Copy-heavy code editing goes further: when the model re-emits or refactors code already in its
context (the daily agent/assistant workload), match-scaled lookup drafts reach 4.5× on Gemma-12B
(75 tok/s) and 3.6× on Ornith-9B (93 tok/s). Any model not listed still gets drafter-free
lookup speculation via --mode auto.
Everything below is also available as a native Mac app — chat with saved sessions, a model manager that answers "will this fit my Mac?" before you download, live speculative-decoding telemetry (per-round acceptance, this machine's measured cost curves), a decoder Race with a checked lossless verdict, one-click coding-agent setup, and a menu-bar gauge with live tok/s and model memory.
brew tap ARahim3/mlx-dspark https://github.com/ARahim3/mlx-dspark
brew trust arahim3/mlx-dspark          # Homebrew 6+: third-party taps need explicit trust
brew install --cask mlx-dspark
xattr -dr com.apple.quarantine /Applications/mlx-dspark.app   # not notarized yet: clear
                                       # quarantine once, or use System Settings › Privacy &
                                       # Security › "Open Anyway" after the first launch
(On Homebrew ≤ 5, brew install --cask --no-quarantine mlx-dspark still works and replaces
the trust/xattr steps — Homebrew 6 removed that flag.)
Or download the DMG from Releases (app-v*
tags) and drag it to Applications. First launch sets up its own private engine runtime (no
Homebrew Python, no venv of yours touched, ~2–4 min once) and keeps the engine on the latest
release automatically; the app itself tells you when a newer app version exists
(brew upgrade --cask mlx-dspark). pip install mlx-dspark stays engine-only — the app is
not in the wheel, and the app never touches a pip-installed engine.
pip install mlx-dspark # or: uv pip install mlx-dspark
Apple Silicon + Python ≥ 3.10; installs mlx ≥ 0.32.0 automatically (0.32's quantized-matmul kernels are what current speedup numbers are measured on). Model weights download from the Hugging Face cache on first use (none bundled). No server framework is pulled in — the API server is built on the standard library.
Known upstream incompatibilities (both handled): mlx-vlm 0.6.5 moved an internal rope-utils module, which crashed
import mlx_dsparkon fresh installs of mlx-dspark ≤ 0.4.2 — fixed in 0.4.3 (both module layouts supported), so upgrade mlx-dspark rather than pinning mlx-vlm. Separately, mlx-vlm 0.6.4 × transformers ≥ 5.12 breaks loading the gemma4 target with a misleadingOSError: Can't load video processor …(#4, upstream Blaizzy/mlx-vlm#1578 — fixed in mlx-vlm 0.6.5). mlx-dspark ≥ 0.3.2 shims that one at load time, so any mlx-vlm ≥ 0.6.3 works; the shim self-retires on fixed releases, andmlx-dspark doctorreports when it is active.
mlx-dspark generate --model mlx-community/Qwen3-8B-8bit --prompt "Explain rainbows."
mlx-dspark serve    --model mlx-community/Qwen3-8B-8bit   # OpenAI + Anthropic API on :8080
That's the whole setup — swap in any target from the table above. Three things worth knowing, then you can stop reading:
--model takes any HF repo or local path (exactly like
mlx-lm); the matching drafter and that pair's measured-best settings resolve automatically.
A model that isn't in the table still gets drafter-free speculation via --mode auto, or pass
--drafter <repo> yourself.--max-draft auto additionally adapts per round while generating (the safest choice if you
only remember one flag); --max-draft N pins a value only if you've measured a better one.mlx-dspark benchmark --model <repo> --trials 3 is the same
reproducible sweep this README's tables come from (the Mac app's Race shows it live, with
a token-by-token identical-output verdict).Prefer clicking to typing? The Mac app wraps all of this — including the calibration and the model picker with "will it fit my Mac?" answered up front.
mlx-dspark serve --model mlx-community/Qwen3-8B-8bit        # → http://127.0.0.1:8080/v1
#   --max-batch 4   continuous batching: up to 4 concurrent requests share each forward
#                   (~2.5× aggregate; a finished request returns immediately, its slot
#                   admits the next one mid-flight)
#   --kv-bits 8     quantized KV cache (long-context bandwidth saver)
#   --mode auto|dspark|dflash|lookup|baseline   ·   --no-thinking   ·   --api-key KEY
#   --reasoning-effort low|medium|xhigh   default reasoning depth on models that support it
#                   (Qwen3.8-class; /health reports support, requests can override)
#   --no-model      start instantly with nothing loaded; POST /admin/load loads later,
#                   POST /admin/unload frees the model again (port survives both).
#                   A first-time load reports download progress in /health and is
#                   cancellable (POST /admin/load/cancel — partials resume by default);
#                   /admin/load also takes per-swap mode / max_draft / lookup_drafts /
#                   confidence_threshold / context_window overrides
--mode auto picks the best available speculation for any target (a known DSpark drafter → else
DFlash → else drafter-free n-gram lookup), so any repo serves with some speedup and no extra flags.
Then point any OpenAI client at it — the speculative speedup is transparent:
from openai import OpenAI
client = OpenAI(base_url="http://127.0.0.1:8080/v1", api_key="not-needed")
print(client.chat.completions.create(
    model="Qwen3-8B-8bit",
    messages=[{"role": "user", "content": "Explain rainbows briefly."}],
).choices[0].message.content)
Works with any OpenAI-compatible client — the same frontends people point at llama.cpp's
llama-server or Ollama work here by switching one setting: set the OpenAI base URL to
http://127.0.0.1:8080/v1 (API key: anything). That covers Open WebUI, SillyTavern,
Continue/Cline, LibreChat, Raycast AI, and the rest of that ecosystem. (There is no GGUF
interop — mlx-dspark runs MLX weights natively — but the HTTP surface is shared, which is the
part those tools actually talk to.)
The server speaks the OpenAI API: POST /v1/chat/completions (streaming and non-streaming,
multi-turn), POST /v1/completions, GET /v1/models, GET /health, GET /metrics. It supports
temperature, top_p, top_k, max_tokens, stop, seed, presence_penalty / frequency_penalty,
logprobs / top_logprobs, tool calling (tools / tool_calls), a per-request thinking toggle
(enable_thinking), and per-request reasoning_effort on models whose template supports it (Qwen3.8-class;
GET /health reports supports_reasoning_effort). Each response carries an x_mlx_dspark block (accept length + tok/s) so the
spec-decode gain is visible. Continuous batching (--max-batch N) serves concurrent requests in one
batched forward for ~2.5× aggregate throughput (see Concurrent throughput);
prefix caching (on by default) reuses the conversation prefix so multi-turn chat and agents don't
re-prefill each turn — measured on an ~8k-token context: first token in ~62 s cold vs 0.2–1 s on
cached turns, hybrid targets included (see Prefix caching).
The same server also speaks Anthropic's Messages API, which is the dialect Claude Code talks — so Claude Code can run entirely on a model on your Mac. Start the server, then in another terminal:
mlx-dspark serve --model mlx-community/Qwen3-8B-8bit --no-thinking   # terminal 1
mlx-dspark claude                                                    # terminal 2
That's it — mlx-dspark claude finds the running server, points Claude Code at it, and hands over
the terminal. Anything after -- goes to claude (mlx-dspark claude -- --continue).
It changes nothing outside that one process. The configuration is passed as the launched
process's environment and nowhere else: no shell profile edited, no settings.json written, no login
replaced. Your other Claude Code sessions — open now or started later — keep their normal account,
model, and endpoint, and this one reverts the moment it exits. Your claude.ai login stays saved and
untouched; Claude Code notes at startup that a credential variable takes precedence over it, which is
just that notice. To wire it up yourself instead, mlx-dspark claude --print-env prints the shell
exports and --print-settings prints a project-scoped .claude/settings.local.json block.
Endpoints: POST /v1/messages (streaming and non-streaming), POST /v1/messages/count_tokens.
Tool calling, multi-turn tool_use/tool_result history, stop_sequences, and system prompts are
translated to whatever the loaded model's own chat template expects — including each family's tool
syntax (Hermes JSON, Gemma-4, and the XML <function=> form) — and a reasoning model's <think> or
<|channel>thought output is lifted into proper Anthropic thinking blocks rather than leaking as
prose.
Measured — each of these ran a real Claude Code session that read a buggy file and fixed it with
the Edit tool (M4 Pro, --no-thinking, identical task):
| target | accept length | prefix cache | wall clock |
|---|---|---|---|
mlx-community/Qwen3-8B-8bit |
3.01 | on — 2 of 3 requests, ~26k tokens reused | ~2:20 |
mlx-community/Ornith-1.0-9B-8bit |
5.07 | off — hybrid target, recurrent state can't be reused | ~4:10 |
mlx-community/gemma-4-12B-it-8bit |
3.68 | on, but its sliding window wraps at this prompt size | ~4:10 |
The ranking is the point: Claude Code sends ~18–26k tokens of system prompt and tool schemas on every request, so prefill dominates wall clock and the target that reuses it wins — Qwen3-8B is nearly 2× faster here despite the lowest accept length of the three. Ornith's 5.07 is the highest acceptance this project has measured anywhere (tool-call JSON is very predictable), but it spends the win on re-prefilling. Choose for prefix-cache compatibility first, drafter quality second.
That table was measured on 0.6.0. 0.7.0 changes its premise for the hybrid row: checkpoint
prefix caching (see Prefix caching) gives Ornith reuse under --no-thinking,
which is the setting this table used — and 0.10.1 drops that condition: stable-boundary
snapshots make checkpoint reuse fire with thinking on and on Qwen3.6/3.8-class templates too, so
every hybrid row's wall clock should improve. Not yet re-measured, so the numbers above stand as
recorded rather than being quietly restated.
The Anthropic endpoint isn't Claude Code–specific. pi
works out of the box against either API — add a custom provider to ~/.pi/agent/models.json:
{ "providers": { "mlx-dspark": {
    "baseUrl": "http://127.0.0.1:8080", "api": "anthropic-messages", "apiKey": "mlx-dspark",
    "models": [{ "id": "Qwen3-8B-8bit", "contextWindow": 40960, "maxTokens": 8192 }] } } }
then pi --provider mlx-dspark --model Qwen3-8B-8bit. (Swap "api" for "openai-completions"
and "baseUrl" for http://127.0.0.1:8080/v1 to use the OpenAI endpoint instead — both work.)
pi is markedly better suited to a local model than Claude Code, for one reason: its system prompt is ~1.5k tokens against Claude Code's ~18–26k. Since prefill dominates, that lands directly on the clock — the same one-bug fix takes ~6 s instead of ~2:20, and a four-tool task (read, two edits, read, write) finishes in 8.5 s at 24 tok/s on Qwen3-8B. Ornith-1.0-9B runs the same task in 18.8 s. Gemma-4-12B doesn't converge on pi's tool protocol (on either endpoint, so it's the model, not the server) — use it with Claude Code instead.
Practical notes for a local model:
| Use a tool-calling model | These are tool-use agents first. Qwen3-8B and up handle it; smaller models flail. |
| Agent choice moves the clock more than model choice | The client's prompt size is the dominant cost on a local model — a lean agent like pi is an order of magnitude faster on the same hardware and the same task. |
--no-thinking is a speed knob, not a requirement |
Leaving it off works fine — reasoning is streamed as proper thinking blocks either way. It just costs: on Qwen3-8B the same Claude Code task ran 3:17 and 2762 output tokens with thinking vs ~2:20 and 169 without, since the model thinks before every tool call. A client sending thinking: {"type": "disabled"} gets the same effect per-request. Note it's a no-op on Gemma-4, whose template doesn't think by default. |
| Leave prefix caching on | It is doing most of the work (see the table). The first request of a cold server is the slow one; since 0.10.1 a fresh session over a system prompt the server has already seen partially reuses it (rungs — see Prefix caching). |
| Context | An over-long request is refused with the wording Claude Code recognises as a context limit, so it compacts and retries instead of dying. --context-window N lowers the bar deliberately (e.g. to keep the KV cache inside your RAM budget). |
| Streams stay alive, and disconnects actually stop generation (v0.12.3) | Keep-alive frames flow every 15 s through stretches with nothing on the wire (long prefills; tool-call responses are buffered until complete), so agent clients don't idle-timeout mid-request. And if a client does vanish, generation stops at the next round instead of running to max_tokens while later requests queue behind it — the "server stalls but /health is fine" failure mode. |
# downloads the drafter + instruct target on first run
mlx-dspark generate --model mlx-community/Qwen3-4B-8bit --prompt "Explain how rainbows form."

# baseline (plain target) vs dspark — same output, faster (record each, stack for a demo)
mlx-dspark generate --model mlx-community/Qwen3-4B-8bit --mode baseline --prompt "..." --max-new-tokens 400
mlx-dspark generate --model mlx-community/Qwen3-4B-8bit --mode dspark   --prompt "..." --max-new-tokens 400

# z-lab DFlash drafter (--max-draft 0 = full 16-block, its native operating point)
mlx-dspark generate --model mlx-community/gemma-4-12B-it-8bit --mode dflash --max-draft 0 --prompt "Write a binary search."

# sampled (not greedy) — lossless w.r.t. the target at temperature T (dspark and dflash)
mlx-dspark generate --model mlx-community/Qwen3-4B-8bit --prompt "Write a short poem." --temperature 1.0 --top-p 0.95 --seed 0
python -m mlx_dspark … works too, and the old flat --prompt … form still maps to generate.
from mlx_dspark import load_pair, speculative_generate

target, tok, drafter, cfg = load_pair("mlx-community/Qwen3-8B-8bit")   # drafter auto-resolved
res = speculative_generate(target, tok, drafter, "Explain how rainbows form.")
print(res.text, res.mean_accept_len, res.tokens_per_sec)
from mlx_dspark import load_dflash_pair, dflash_generate   # z-lab DFlash instead

target, tok, drafter, cfg = load_dflash_pair("mlx-community/gemma-4-12B-it-8bit")
res = dflash_generate(target, tok, drafter, "Write a binary search in Python.")  # max_draft_tokens=None = full block
print(res.text, res.mean_accept_len, res.tokens_per_sec)
Pass any target repo/path to --model; the matched drafter auto-resolves for the targets below
(quantization-agnostic — a -4bit / -8bit / -bf16 of the same model resolves the same drafter). For
anything else, add --drafter <repo>. Run mlx-dspark models to print this table.
target (--model) |
DSpark drafter (--mode dspark) |
DFlash drafter (--mode dflash) |
peak RAM | + cache at 128k ctx |
|---|---|---|---|---|
mlx-community/Qwen3-4B-8bit |
deepseek-ai/dspark_qwen3_4b_block7 |
z-lab/Qwen3-4B-DFlash-b16 |
~8 GB | not measured yet |
mlx-community/Qwen3-8B-8bit |
deepseek-ai/dspark_qwen3_8b_block7 |
z-lab/Qwen3-8B-DFlash-b16 |
~11 GB | not measured yet |
mlx-community/gemma-4-12B-it-8bit |
deepseek-ai/dspark_gemma4_12b_block7 |
z-lab/gemma4-12B-it-DFlash |
~15 GB | not measured (partly window-bounded) |
prism-ml/Ternary-Bonsai-27B-mlx-2bit |
Rahim/Ternary-Bonsai-27B-dspark |
— | ~12 GB | not measured yet |
mlx-community/Qwen3.6-27B-8bit |
satgeze/Qwen3.6-27B-DSpark (community) |
— | ~32 GB | ~11 GB (est., same arch as Qwen3.8) |
mlx-community/Qwen3.8-27B-4bit3 |
DimInfer/Qwen3.8-27B-Dspark-v1 (community, 4-bit-class) |
— | ~18 GB | ~11 GB measured (~23 GB at full 256k) |
mlx-community/Qwen3.8-27B-8bit3 |
RadixArk/Qwen3.8-27B-DSpark (community, SpecForge) |
— | ~29 GB | ~11 GB measured (~23 GB at full 256k) |
mlx-community/Ornith-1.0-9B-8bit |
stanleyphoong/Ornith-1.0-9B-DSpark (community) |
— | ~13 GB | not measured yet |
mlx-community/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-4bit |
mlx-community/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-DSpark-bf16 (NVIDIA head, MLX) |
— | ~20 GB | not measured yet |
mlx-community/Muse-Glimmer-30B-4bit |
DaoCloud/Muse-Glimmer-30B-DSpark (community, DFlash-lineage) |
— | ~26 GB (4-bit) / ~40 GB (8-bit1) | not measured yet |
Peak RAM is measured on an M4 Pro (8-bit target + 4-bit drafter + KV cache) at chat-length
context; add headroom for macOS. Cache at 128k ctx is what a long-context session adds on
top: the target's attention KV plus the drafter's context cache grow linearly with every
token of context. The Qwen3.8-27B figure is measured on-device (0.086 GB per 1k tokens —
64 KB/token target KV + 20 KB/token drafter ctx, matching the architecture math exactly:
16 full-attention layers × 4 KV heads × 256 head-dim in bf16; the 48 linear-attention layers
hold fixed-size state, which is why a 27B "256k-context" model is usable at long context on
a Mac at all) and is the same for both quants — the cache is bf16 regardless of weight bits.
So Qwen3.8-27B-4bit at 128k needs ~26 GB total, the 8-bit ~40 GB; --kv-bits 8 roughly
halves the attention-KV share. Cap it with --context-window (or the context_window
override on /admin/load) when RAM is the constraint — requests past the cap get the
"prompt is too long" error agent clients auto-compact on.
Rows marked (community) use drafters published by the community, not by DeepSeek — quality varies more
than with the official checkpoints, and it shows up directly as acceptance length (= your speedup).
The Ornith drafter is the strong case: rigorously qualified by its author (17/17 gates, 95% of the
DSpark paper's reference acceptance) and it produces the best chat speedups in this table. The
Qwen3.6-27B drafter is the other strong one: block-15, trained against the bf16 target and
warm-started from z-lab's DFlash head for it. Its row is measured on the 8-bit target; a -4bit
target resolves the same drafter and, by the pattern every other model here follows, should trade
ratio for absolute tok/s — that combination is not measured.
A 4-bit target (--model …-it-4bit) roughly halves the target's share (fits smaller Macs). Use the
matched instruct target the drafter was trained against — a base model drops acceptance sharply. The
legacy --family qwen3|gemma4 flags still work but are deprecated in favor of --model.
Already use LM Studio? Its MLX downloads are reused automatically: pass the same
publisher/model id LM Studio shows (e.g. --model lmstudio-community/Qwen3-8B-MLX-8bit) and
the engine loads it straight from LM Studio's folder (~/.lmstudio/models) instead of
re-downloading — they also appear in mlx-dspark models and the app's "On this Mac" list.
Only MLX downloads work this way; LM Studio's GGUF files are a different format our
loaders don't read (grab the mlx-community version of the same model instead). The reverse
direction — using mlx-dspark as an engine inside LM Studio's chat window — isn't possible
(LM Studio only runs its own bundled engines), but the server speaks the standard OpenAI API,
so any client that takes a custom OpenAI endpoint can point at it.
--drafter lets you run any other matched z-lab / DeepSpec checkpoint with no code change and no
registry entry — the registry only saves you from having to name the drafter:
# a pair we have measured -> the drafter auto-resolves
mlx-dspark generate --model mlx-community/Qwen3-14B-8bit --prompt "Explain how rainbows form."

# anything else -> name the drafter yourself; identical machinery from here on
mlx-dspark generate --model mlx-community/Qwen3-32B-8bit \
  --drafter deepseek-ai/dspark_qwen3_32b_block7 --prompt "Explain how rainbows form."
New DSpark/DFlash drafters keep landing on HF in three different packagings; here is the honest compatibility contract (loaders refuse incompatible checkpoints with an error naming the reason, never a silent mis-load):
| checkpoint style | example | status |
|---|---|---|
| DeepSpec-native standalone drafter (qwen3/gemma4 backbone, any size/quant) | deepseek-ai/dspark_qwen3_32b_block7 |
✅ runs via --drafter — no registry entry needed (4B/8B/14B/gemma-12B are measured and registered, so they need no flag; larger sizes should run — reports welcome) |
| z-lab DFlash adapter for a qwen3/gemma4-family target | z-lab/Qwen3-8B-DFlash-b16 |
✅ runs via --mode dflash --drafter |
| DFlash 2 (Inco AI: candidate selector + dynamic convs) | incoai/Qwen3.8-27B-DFlash2 |
✅ runs via --mode dflash --drafter; the Qwen3.8-27B heads are measured and registered (auto-resolve, and --mode auto picks them as that target's best) |
| PrismML dspark GGUF (Bonsai-27B) | prism-ml/Ternary-Bonsai-27B-gguf → *-dspark-bf16.gguf |
✅ pre-converted repacks auto-resolve (Rahim/*-dspark); any future GGUF-only drop runs via --drafter gguf:<repo>/<file>.gguf (converted locally, once) |
vLLM "speculators" format (dspark algorithm) |
makora-ai/gemma4-26b-a4b-dspark, mgoin/Qwen3-8B-speculator.dspark |
✅ runs via --drafter — the config schema is translated on load (the tensor names are already DeepSpec's). Includes EAGLE-3-style reduced draft vocabularies (draft_vocab_size + a d2t table). Other speculators algorithms (eagle/eagle3) are refused by name. makora-ai/gemma4-26b-a4b-dspark (Google's 26B/4B-active MoE) measures 1.27× on mlx-community/gemma-4-26b-a4b-it-8bit (--max-draft 2 --no-lookup-drafts: 1.38× code / 1.37× math / 1.06× chat, 46.9→59.5 tok/s) — not registered for auto-resolution while the ratio is under review |
| Full model with embedded drafter | deepseek-ai/DeepSeek-V4-Pro-DSpark (893 GB, MLA+MoE) |
❌ different architecture & packaging — out of scope for consumer Macs |
| DFlash+Markov community hybrids | Hikari07jp/DSpark-Gemma-4-31B-draft |
❌ hybrid head — not yet |
Targets: any dense mlx-lm text model routes automatically; a one-time load probe verifies the
hidden-state tap reproduces the model's own forward and fails loudly if the family needs bespoke
support (drafter-free --mode lookup / --mode auto still work with any target). If you run a
pair we haven't measured, mlx-dspark benchmark --json produces a device-stamped result we can fold
into the table — please share it.
Very small targets are not worth a drafter. Speculation buys time in proportion to what one
target step costs, so below ~4B there is little to win. Measured, so you don't spend the download:
satgeze/Qwen3.5-0.8B-DSpark on
Qwen3.5-0.8B-8bit runs correctly and losslessly but comes out at 0.96× — the target is already
215 tok/s, and a draft round costs nearly as much as the step it skips. Run these models plain.
Bonsai 27B is PrismML's 1.7-bit ternary (and 1-bit) rebuild of Qwen3.6-27B — a full 27B-class reasoning model in ~8 GB. It ships with a DSpark drafter that PrismML publishes GGUF-only and, per their own docs, accelerates their CUDA path but "not Macs yet". mlx-dspark runs it on a Mac:
mlx-dspark generate --model prism-ml/Ternary-Bonsai-27B-mlx-2bit \
  --max-draft auto --prompt "Implement binary search in Python."
# first run: downloads the target (8.5 GB) + the matched drafter (6.8 GB bf16 safetensors —
# our 1:1 repack of PrismML's GGUF-only drafter, quantized to 4-bit at load)
Measured on an M4 Pro 48 GB (greedy, warm): baseline ~25.5 tok/s; ~1.15× on code/structured content (acceptance ~2.9/round at cap 2), ~break-even on open chat. Output is lossless — byte-identical to plain greedy decoding. Bonsai's backbone is hybrid linear attention (48 of 64 layers carry recurrent state, which can't be rolled back like a KV cache), so mlx-dspark records each verify round's recurrence inputs and, on a partial accept, rebuilds the state at the exact accept point (bit-exact, a few ms) — rejected drafts cost about as little as a dense KV trim. As far as we know this is the first working speculative decoding for this model family on Apple Silicon.
Two honest caveats. The ceiling is the 2-bit quantization itself: extra verify rows on a
2-bit model are compute-bound (they cost the same as on a 4-bit model, measured), while its
plain step is very fast — so chat-level acceptance hovers at break-even instead of the
1.6–2.1× the 8-bit presets reach. --max-draft auto stays the recommended setting: it
picks the cap from this machine's measured curves + live acceptance and can still park
speculation (plain pipelined steps + probe rounds) on content where it would lose. And it
requires mlx ≥ 0.32.0 (older mlx lacks the multi-row 2-bit matmul path that makes
verification affordable at all). Prefix caching works here too via checkpoint mode — the
recurrent state can't trim, so it's snapshotted at boundaries instead (see
Prefix caching) — and baseline batching handles hybrids since 0.7.0;
only batched speculative decoding stays dense-only.
Baseline/--mode lookup also work for any other qwen3_5 (Qwen3.5/3.6-family) checkpoint.
The 1-bit Bonsai-27B-mlx-1bit pack runs on stock MLX as of mlx-vlm 0.6.5 (which
ships a Python-hosted 1-bit kernel; stock mx.quantize still has no 1-bit mode) — but
speculative decoding measures a net loss on it: that kernel re-reads the full weight
stream once per verified token, so verify cost is linear in draft length, and dspark lands at
0.71–0.77× baseline at every cap (M4 Pro, healthy acceptance, losslessness intact). mlx-dspark
therefore keeps the pack unintegrated — plain generation via mlx-vlm ≥ 0.6.5 is the right tool
for it (~35 tok/s on an M4 Pro vs ~25 for the ternary), and load_target refuses it with a
pointer saying so. The ternary 2-bit variant remains the speculative-decoding operating point.
--mode dflash) — a block-diffusion drafter that denoises a whole 16-token block in one
parallel pass and reuses the target's own embed/lm-head. Different trade-offs (see below).--temperature > 0 switches to lossless speculative
sampling — an exact sample from the target at temperature T (with --top-p / --top-k).The drafter loads 1:1 from the HF checkpoint and is 4-bit quantized by default (cheap to run each round; quantization doesn't change acceptance — that's set by the drafter↔target match).
Mode first, because it's the short one: --mode auto picks each pair's measured best.
That is DSpark everywhere except Qwen3.8-27B, where the DFlash 2 drafter wins on both quants
(same verify width, higher acceptance — receipts in
DSpark vs DFlash). The original-DFlash verdict is
version-dependent and worth knowing about: on mlx 0.31, verify cost rose steeply with the
number of tokens verified, which made DFlash's full 16-block the winner on Gemma-12B code/math;
0.32's kernels made narrow multi-row verify disproportionately cheaper and flipped it to DSpark —
and v0.12.0's small-M verify kernel flattened the curve enough that DFlash 2's
acceptance-at-fixed-width wins it back on Qwen3.8. If your mlx/hardware differs,
--max-draft auto re-measures the curves on your machine, and mlx-dspark benchmark settles it
empirically.
Target, by the Mac you have (all numbers from the table above; speedups and caps are this M4 Pro's — yours are derived fresh on first run):
Qwen3.8-27B-8bit (best ratio in the project: 3.63× with its DFlash 2
drafter, 4.06× on math — --mode auto picks it) or Muse-Glimmer-30B-8bit (the strongest
DSpark chat ratio, 2.2×+). Both ~29–40 GB resident.Qwen3.8-27B-4bit (27B quality in ~18 GB at ~25–38 tok/s, the fastest
decode here — DFlash 2 via --mode auto, no cap flag needed), gemma-4-12B-it-8bit
(big ratio and real speed: ~46–55 tok/s), or Qwen3.6-27B-8bit.Ornith-1.0-9B-8bit (2.4× at ~59–68 tok/s, the mid-size sweet spot),
Qwen3-8B-8bit, or Qwen3-4B-8bit (~87–101 tok/s, fits ~8 GB).Qwen3.6-35B-A3B-4bit (~91–145 tok/s).
Their speedup ratio is modest for a structural reason (sparse targets are already fast —
see the MoE note under Results), but nothing here decodes faster.Qwen3-8B-8bit wins wall-clock in the
Claude Code comparison, and since v0.10.1 the hybrid targets
(Qwen3.8/Qwen3.6/Ornith) cache too. Use --no-thinking and an 8B+ tool-calling model.For target precision: 8-bit is the sweet spot (best acceptance + quality); 4-bit gives the highest absolute throughput and fits smaller Macs but a smaller speedup ratio; bf16 is slower on M-series (verify dominates). The drafter stays 4-bit either way. Full numbers and the reasoning are in Benchmarks & deep dive.
On copying caps and flags from these tables. Every cap and flag shown is this M4 Pro's derived optimum for that exact quant — a starting point, not a setting to paste in. Two things that trip people up:
--max-draft, mlx-dspark derives it from your machine's own
curves (per model + quant + mlx version). A faster, higher-bandwidth machine can land lower,
not higher — an M5 Max may pick cap 2 for the 8-bit 27B where this M4 Pro picks 7, because
cheaper verify shifts the optimum down, and forcing 7 there is a small net loss. Prefer no
flag, or --max-draft auto.--confidence-threshold is drafter-specific, not just quant-specific. It only pays when
the drafter leaves acceptance headroom for early truncation to recover. The previous 4-bit
head (RadixArk) did, and gained from --max-draft 7 --confidence-threshold 0.3; the shipped
4-bit head (DimInfer) accepts too well (3.3–5.3/round) for it to help — plain cap 7, no
confidence flag is its best, and 0.5 measures worse. The 8-bit RadixArk head is flat
under the small-M kernel and also wants cap 7 with no flag. Each row's per-content badge is its
own; don't paste a flag across quants or drafters.DSpark vs plain greedy decoding of the same model, each at its own measured cap (M4 Pro 48 GB,
warm, 8-bit instruct target, 4-bit drafter, mlx 0.32.0). Regenerated 2026-07-22 with
mlx-dspark benchmark --trials 3 (Muse row 2026-08-12, post-0.8.1 drafter truncation; Qwen3.8
8-bit row 2026-08-16 with the small-M verify kernel; Qwen3.8 4-bit row 2026-08-18 on the
DimInfer drafter, --max-draft 7, no confidence): every number
is a median of 3 runs over the harness's three prompts, and the tok/s columns are the mean across
them. Reproduce any row with that command.
The cap column is the headline change, twice over. mlx 0.32's quantized-matmul kernels widened
the cheap verify region to width 5 for 8-bit weights — so the old hard-coded cap=2 was leaving
10–35% on the table for every 8-bit target. Then v0.12.0's small-M verify kernel removed
the cliff that sat after that region (stock quantized_matmul re-pays the whole weight read
per row at 2–8 rows — see the ceiling section), which is
how the Qwen3.8-27B rows reach cap 7. The cap is never hard-coded: it is derived from each
machine+model+quant's measured cost curves (see Tuning), which is why Bonsai sits at
2, most 8-bit rows at 4, and the kernel-flattened rows at 7 — same code, different measured
curves.
| target | cap | accept len | baseline | mlx-dspark | speedup | chat / code / math |
|---|---|---|---|---|---|---|
| Gemma-4 12B | 4 | 3.95 | 17.8 tok/s | 49.4 tok/s | 2.78× | 2.63× / 2.61× / 3.09× |
| Qwen3.8-27B (8-bit, hybrid)53 | 7 | 4.05 | 8.3 tok/s | 22.6 tok/s | 2.72× | 1.95× / 2.84× / 3.37× |
| Muse-Glimmer-30B (8-bit, dense)1 | 4 | 3.31 | 8.2 tok/s | 20.2 tok/s | 2.47× | 1.97× / 2.45× / 2.99× |
| Ornith-1.0-9B (hybrid)5 | 4 | 3.64 | 26.7 tok/s | 64.2 tok/s | 2.40× | 2.21× / 2.53× / 2.48× |
| Qwen3.6-27B (8-bit, hybrid)56 | 4 | 3.15 | 8.4 tok/s | 19.2 tok/s | 2.29× | 2.26× / 1.96× / 2.67× |
| Qwen3-8B | 4 | 2.94 | 28.1 tok/s | 57.7 tok/s | 2.05× | 1.81× / 2.06× / 2.29× |
| Qwen3-14B7 | 4 | 2.87 | 15.3 tok/s | 31.0 tok/s | 2.03× | 1.62× / 2.11× / 2.36× |
| Qwen3.8-27B (4-bit, hybrid)53 | 7 | 4.49 | 14.8 tok/s | 29.5 tok/s | 1.99× | 1.51× / 2.14× / 2.31× |
| Qwen3-4B | 4 | 2.79 | 50.9 tok/s | 92.4 tok/s | 1.82× | 1.77× / 1.70× / 1.98× |
| Qwen3.6-35B-A3B (4-bit, MoE, hybrid)52 | conf | 4.72 | 86.9 tok/s | 114.5 tok/s | 1.32× | 1.05× / 1.24× / 1.67× |
| Nemotron-3.5-Lightning-30B-A3B (4-bit, MoE+Mamba, hybrid)4 | 3 | 3.28 | 91.4 tok/s | 100.9 tok/s | 1.10× | 0.95× / 1.23× / 1.13× |
| Ternary-Bonsai-27B (2-bit, hybrid) | 2 | 2.60 | 25.4 tok/s | 27.2 tok/s | 1.07× | 1.01× / 1.13× / 1.07× |
The table above is DSpark-mode; on Qwen3.8-27B the DFlash 2 drafter
(incoai/Qwen3.8-27B-DFlash2) beats the
DSpark heads at the identical verify width (cap 7 = full block, the dflash-mode default),
so --mode auto — and the Mac app — resolve it for both quants. Same-session pairs, 3-trial
medians, small-M kernel on, 200 tok:
8-bit (baseline 8.4 tok/s):
| method (cap 7) | mean | chat | code | math | accept | tok/s |
|---|---|---|---|---|---|---|
DSpark (RadixArk) |
2.92× | 1.99× | 3.24× | 3.55× | 4.15 | 24.5 |
| DFlash 2 | 3.63× | 2.79× | 4.05× | 4.06× | 5.53 | 30.5 |
4-bit (baseline 14.7 tok/s, ~18 GB):
| method (cap 7) | mean | chat | code | math | accept | tok/s |
|---|---|---|---|---|---|---|
DSpark (DimInfer) |
2.01× | 1.57× | 2.21× | 2.27× | 4.41 | 29.6 |
| DFlash 2 | 2.30× | 1.68× | 2.62× | 2.63× | 5.14 | 33.8 |
DFlash 2 adds a candidate path selector (top-16 target-head candidates per slot, a bilinear lattice walked from the verified anchor) and per-sublayer dynamic convolutions to the DFlash backbone — acceptance rises ~+1.1–1.4 tokens without widening the verify, which is exactly the kind of gain that converts on Apple Silicon (the small-M kernel made verify width 8 nearly flat on these targets). Greedy-lossless like everything here (the only divergences from single-row greedy are fp ties at margins 0.0–0.125), sampled decoding stays lossless through the selector's own proposal distribution, and prefix caching covers this mode (identical-repeat TTFT 159×, multi-turn 29×, outputs byte-identical to the cold runs). The win is smaller at 4-bit than 8-bit (1.14× vs 1.24× over DSpark) because the 4-bit verify curve still rises to width 5 — the acceptance converts less efficiently, as the curve predicts.
The MoE row is the interesting one, and its lesson is about the baseline, not the drafter. Qwen3.6-35B-A3B activates ~3.8B of its 35B parameters per token, so plain greedy decoding already runs at 86.9 tok/s — faster than every other target here, including the 4B. The drafter is good: acceptance reaches 7.0 tokens/round on math, the highest this project has measured. It still only converts to 1.32×, because speculation's value scales with what a target step costs, and here a step is only ~11.5 ms while the drafter — 1.53B dense parameters, against a target with 3.8B active — costs ~5.7 ms of every round. Two other things follow from the same fact and are specific to this row:
--lookup-drafts
forces it back on.--confidence-threshold 0.3 (0.5 is within noise of it; 0.7 over-throttles, back to 1.21×).
The rule this generalized to — refined once more by the Qwen3.8-27B rows: confidence pays
iff the verify curve still rises inside the cap's window and the drafter leaves acceptance
headroom for truncation to recover. The RadixArk 4-bit head (rising curve to width 5,
modest acceptance) gained from cap 7 + 0.3; its 8-bit sibling (flat 1–8 under the kernel)
measures worse with it. But the shipped 4-bit head, DimInfer, has the same rising curve
yet accepts 3.3–5.3/round — no headroom left — so confidence buys nothing there either. Same
curve, opposite verdict: the verify shape is necessary, not sufficient.Drafter quantization was swept for this pair and 4-bit remains right — 3-bit is no cheaper
(the drafter's cost is dominated by a 248K-vocab head, not by weight bytes) and 2-bit and 8-bit
are both slower. Prefill's wide-GEMM lever gives only 1.03× here (905 → 931 tok/s,
bit-identical) rather than the usual 1.07–1.15×, because the MoE expert weights are
SwitchLinear rather than QuantizedLinear and the optimization never sees them. Turn-2 prefix
reuse used to miss here: the Qwen3.6 chat template prefills a <think> opener, so the next
turn's prompt landed 2 tokens short of the checkpoint boundary (4 with --no-thinking).
0.10.1's stable-boundary snapshots fix exactly this — the server measures each template's
re-render-unstable tail and snapshots below it, so turn-2 reuse now fires (see
Prefix caching).
Most 8-bit rows peak at cap 4 and fall off sharply at cap 5 — the cliff sits exactly where the measured verify curve leaves its cheap region (width 5 → 6). The Qwen3.8-27B rows are the exception that proves the mechanism: v0.12.0's small-M kernel removes that cliff for 4/8-bit group-64 weights, the re-measured curve comes back flat through width 8, and the derived cap moves to 7 on its own (the other 8-bit rows predate the kernel and will be re-measured with it). Bonsai is the counter-example at the other end: its 2-bit verify cost climbs from width 2, so it peaks at cap 2 (cap 1 = 1.00×, cap 3 = 1.06×) and there is no wide-draft regime to reach.
Baselines are this harness's pipelined greedy loop, which measures at parity with mlx_lm.generate
(the Qwen3-4B baseline is the same 51–52 tok/s either way). All paths produce identical output to
plain decoding — they're just faster. Chat content accepts less than code everywhere; on the 2-bit
Bonsai target chat lands ~break-even (its verify rows are compute-bound), and --max-draft auto
adapts or parks where speculation would lose (see the Bonsai section). Why a Mac can't go much
higher and the cost model are below.
The table is fresh-generation content. On copy-heavy editing — the model re-emitting or refactoring code already in its context — match-scaled lookup drafts (0.5.0, on by default) go well past it: Gemma-12B file re-emission 3.03× → 4.51× (75 tok/s), rename-refactor 4.33×; Ornith-9B rename-refactor 2.79× → 3.57× (93 tok/s), re-emission 2.45× — outputs still bit-identical, chat and fresh code unchanged. See the hybrid-drafting bullet in Flags that matter for how it works. The deep-dive's multi-prompt DSpark-vs-DFlash tables are mlx-0.31.2-era and are kept as the last full sweep — 0.32 shifted that balance toward DSpark (spot-checked; see that section's note).
Everything above measures decode — how fast tokens come out once generation starts. The other half of your wall clock is prefill: reading the prompt. For a chat message that is nothing; for a pasted file, a long conversation, or an agent (Claude Code sends ~18–26k tokens every request) it is most of the time you wait.
Measured on an M4 Pro, ~3.2–3.7k-token prompt, median of 3, default settings:
| target | prefill | a 20k-token prompt takes |
|---|---|---|
| Qwen3.6-35B-A3B (4-bit, MoE) | 960 tok/s | ~21 s |
| Qwen3-4B (8-bit) | 761 tok/s | ~26 s |
| Qwen3-8B (8-bit) | 438 tok/s | ~46 s |
| Gemma-4 12B (8-bit) | 264 tok/s | ~76 s |
| Qwen3.8-27B (8-bit) | 133 tok/s | ~151 s |
| Qwen3.6-27B (8-bit) | 126 tok/s | ~159 s |
The MoE tops this table despite being the largest model in it: prefill is compute-bound, and an A3B model does only ~3.8B parameters' worth of arithmetic per token no matter how many experts it stores. The same fact shows up on Qwen3.8-27B the other way: its 4-bit quant prefills at the same 135 tok/s as the 8-bit — weight bits change decode speed (bandwidth-bound), not prefill.
Since 0.7.0 mlx-dspark skips the prefill logits every caller discards and dequantizes wide weights
once instead of per output tile, which is worth 1.07–1.15× here — bit-identical, no extra
peak RAM, on every target and both model routes. The one exception is that MoE row, where it is
worth only 1.035× (928 → 960 tok/s): the optimization hooks nn.QuantizedLinear, and an MoE
keeps most of its weight in SwitchLinear experts that it never sees. Extending it to the
gather path is open work. Prefill runs at ~85% of this machine's measured
bf16 GEMM peak (and so does attention), so that is close to all there is to take: the remaining
lever is not prefilling at all, which is what prefix caching does.
That makes the table's "20k-token prompt" column a first-request cost, not a per-request one: in multi-turn chat or an agent loop, every turn after the first reuses the cached prefix and skips straight to decoding. Measured on Qwen3.8-27B (a hybrid, ~8k-token system prompt): first token in ~62 s cold → 0.21 s on a retry, ~1 s on the next conversation turn — and since 0.10.1 that includes hybrid GDN/Mamba targets on thinking templates, plus partial reuse when a new session shares only the system prompt.
--max-batch N runs up to N concurrently-queued requests through one batched target forward, so
they share a single weight-read per step — the regime where speculative decoding really shines. For a
local agent swarm (a few agents hitting the server at once) this is a large aggregate win, and single
requests are unaffected: a lone request — or one using penalties / logprobs / temperature > 0 dspark —
takes the serial path, so per-request latency never regresses.
Batching is continuous (dspark): a request is delivered the moment it finishes — it never waits
for the batch's slowest member — and its freed slot admits the next queued or newly-arriving request
mid-flight (measured: a short request joining two long ones returned at 2.3 s while they ran to 8.4 s).
With --max-draft auto, the cap is also calibrated per batch width: at B=4 the measured verify
curve flattens past the qmm knee (the paper's cheap-verify regime), so longer draft blocks pay again
(+5% aggregate at B=4 from the auto-picked cap on an M4 Pro).
Qwen3-4B-8bit, M4 Pro, 4 concurrent requests, mlx-0.31.2-era sweep (aggregate tokens/s vs the greedy baseline run serially; the batched-vs-serial ratios are the durable part — absolute levels are higher on 0.32):
| serving | aggregate tok/s | vs serialized baseline |
|---|---|---|
| greedy baseline (one at a time) | 52 | 1.00× |
batched baseline (--mode baseline --max-batch 4) |
128 | 2.48× |
batched dspark (--mode dspark --max-batch 4) |
130 | 2.51× (1.73× over serialized dspark) |
Both the target verify and the DSpark drafter are batched. Output stays greedy-correct per request; a batched quantized target is not bit-identical to single-sequence decoding (the quantized matmul takes a different numeric path at batch width — the same qmv→qmm knee as the cost model below — flipping ~0.5% of near-tie tokens), which is inherent to any batched quantized server, not spec-specific.
Batching used to require a model whose every layer holds a plain KV cache, which excluded every hybrid target — Ornith, Bonsai, Qwen3.6-27B, Qwen3.6-35B-A3B — because most of their layers hold recurrent linear-attention state instead. It turns out that state is the easy case: it is a fixed-size summary, not a per-token buffer, so rows of different prompt lengths merge by plain concatenation, with no padding and no per-row offsets. Only the minority attention layers need the left-aligned per-row cache that already existed.
Aggregate tok/s, 8 varied prompts, 96 tokens each, M4 Pro (batched vs the same prompts run one after another):
| target | B=2 | B=4 | B=8 |
|---|---|---|---|
| Qwen3-4B-8bit (dense) | 1.70× | 3.05× | 4.00× |
| Ornith-1.0-9B-8bit (hybrid) | 1.94× | 3.52× | 3.08× |
| Qwen3.6-35B-A3B-4bit (hybrid MoE) | 1.30× | 1.73× | 2.11× |
The MoE amortizes worst, not best — which is the opposite of the intuition that a sparse model has more to gain. A dense model's batch rows share its entire weight read; an MoE's rows share only the ~2.8B non-expert parameters, and every additional row pulls in a fresh set of routed experts. Sparsity is what makes an MoE fast at batch 1, and it is the same property that leaves it less to amortize at batch N.
Batching and speculation are substitutes here, not complements. Once batching has filled the
machine, extra verify width is no longer cheap: measured verify(width 4)/verify(width 1) rises
from 1.11× at B=1 to 2.10× at B=16 on Qwen3-4B. End to end at B=4 on that model, batched dspark
lands at 0.97× of batched baseline — a wash. Speculation's value is largest for a single
stream; batching's is largest for many. The drafter card's own CUDA numbers show the same shape
(2.9× solo → 1.9× at capacity).
Batched speculative decoding stays dense-only. A spec round rolls each row back by a different amount, which is per-row metadata on a KV cache but has no equivalent for recurrent state — the single-row path rebuilds it by re-running the recurrence, and doing that at a different length per row needs a masked batched re-run that does not exist yet. So a hybrid target batches its baseline and takes the serial path for dspark; nothing silently degrades. Gemma-4 (mlx-vlm, rotating cache) still falls back to serialized entirely.
The server keeps the target KV cache (and, for DSpark, the drafter context) from the previous turn and reuses the shared conversation prefix instead of re-prefilling it. On a ~750-token shared context this makes follow-up turns ~13× faster (measured: 87 ms vs 1132 ms). It's lossless to the same standard as the rest of the project (a warm turn differs from a cold one only at logit-margin≈0 ties) and invalidates itself on any error so it can't desync.
On by default for every mode — dspark / baseline / lookup, and (since 2026-08-19)
dflash too, checkpoint-only: the DFlash drafter's context is recoverable from a bounded
window of projected rows (its sliding-window attention sees at most window − 1 of them,
~21 MB on Qwen3.8-27B), which is snapshotted at the boundary and replayed into fresh drafter
caches on a hit. Measured with the DFlash 2 pair (~4k-token system prompt): identical-repeat
TTFT 38.3 s → 0.24 s (159×), next conversation turn 31.1 s → 1.08 s (29×), outputs
byte-identical to cold runs and drafter acceptance preserved. It runs in one of two modes,
picked automatically — you don't choose:
Checkpoint reuse used to be all-or-nothing at the exact prompt boundary, which in practice meant
it almost never fired (issue #7): thinking-style chat templates re-render the <think> opener so
turn N+1 misses the boundary by 2–4 tokens, and a byte-identical retry couldn't hit at all. The
server now measures each chat template's stable boundary at runtime and snapshots there, and
adds two partial-reuse mechanisms for hybrid recurrent targets:
--prefix-cache-rungs tokens (default 8192) the recurrent state (small
and fixed-size) is also snapshotted mid-prefill; the attention KV and drafter context are
trimmable, so a request that diverges mid-prompt (a new session on the same system prompt,
compacted history) reuses the cache up to the nearest rung instead of missing outright.Measured (Qwen3.8-27B-4bit, ~8k-token system prompt, M4 Pro): time-to-first-token 62 s cold → 0.21 s on an identical retry, 1.05 s on the next conversation turn, 0.53 s for a "same system prompt, new user" request after its anchor is planted — with outputs byte-identical to the uncached server. Restores are bit-exact (validated array-for-array on device); a miss still costs nothing.
Flags: --no-prefix-cache, --prefix-cache-slots N (LRU slots so a chat and
an agent don't evict each other, default 2), --prefix-cache-rungs N (partial-reuse spacing,
0 disables), and --prefix-cache-dir DIR + --prefix-cache-max-ram-mb N
for the optional SSD spill tier on very long contexts.
Everything below is for readers who want the numbers and the why. The sections above are enough to use it.
Reproduce the sweep on your own Mac with mlx-dspark benchmark --model <repo> (warm, device-stamped, --json).
Speculative decoding amortizes a memory-bound single-token decode across the K tokens verified in one
forward. On a datacenter GPU that arbitrage is huge (parallel verify is nearly free, so speedup ≈ acceptance
length). On an M-series chip it's weaker — verify cost grows with the number of tokens verified
(multi-token verify leaves the quantized matmul's cheap few-rows path). The cost model is
tok/s ≈ A / (drafter + overhead + slope·C) for accept length A and draft cap C; the slope is a
property of (quantization × mlx version × chip), which is why --max-draft auto measures it on your
machine instead of trusting a constant. On mlx 0.31.2 we measured ≈ +14 ms/token for Gemma-4 12B (a
~2.2× ceiling even with a perfect drafter); mlx 0.32's kernels flattened the curve enough that Gemma-4
now measures 2.11× at cap 2 — past what the old curve allowed.
v0.12.0 moved the wall itself. The rising verify cost was never hardware: MLX's stock
quantized_matmul re-reads (and re-dequantizes) the whole weight matrix per row for 2–8 rows —
exactly the verify window — and only amortizes it from ~13 rows up
(ml-explore/mlx#4265). mlx-dspark now ships a small
simdgroup_matrix kernel (vendored MIT from avlp12's fork, see
NOTICE) that reads each 4/8-bit weight group once and reuses it across all rows: verify widths 6–8
drop to ~width-5 cost (measured 1.3–1.7× per matmul, flat in width). That is what pushed
Qwen3.8-27B-8bit to 2.72× at a derived cap of 7 and its 4-bit sibling past 2× on code — and per
project doctrine it is gated per shape by a one-time on-device probe, so on a machine or mlx version
where it doesn't win, it silently stays off. The binding limiter remains acceptance
length (set by the drafter↔target match) — not drafter quantization (4-bit / 8-bit / bf16 give
identical acceptance; 4-bit is simply fastest).
The verify width now adapts to context depth (2026-08-20, unreleased). Verify cost is not
depth-flat: with 2–8 rows Metal's attention kernel re-reads the whole KV cache once per row, so a
wide verify that is free at chat depth gets expensive at agent depth — measured on Qwen3.8-27B-4bit
(M4 Pro, decode-only, same accept), the fixed cap-7 configs fell from 1.17–1.41× at 2k context to
0.53–0.97× (net loss) at 32k, while cap 3 at 32k still gives 1.48×. So calibration now also
measures each pair's per-width depth slope (one-time, cached), and both the derived default cap and
--max-draft auto price it: short prompts keep the measured chat-depth optimum untouched, long prompts
shrink the verify width automatically. A cap you set explicitly is never overridden. (History: before
v0.3.1 the drafter also had a depth-scaling bug — redundant GQA/KV tiling — fixed bit-identically;
the 2026-08-20 finding is the verify side, and it explains "slows down a lot on large context" reports
with DFlash 2/DSpark at coding-agent context sizes.)
Two things do still grow with a longer prompt, for every decoder (baseline, mlx-lm, this) — not the
speculative speedup: time-to-first-token (reading an L-token prompt is inherent work) and per-token
decode (attention reads a longer KV cache). Prefix caching (on by default) is the lever for the first.
--kv-bits 8 halves the KV RAM (and now works on the hybrid Qwen3.6/3.8/Ornith-class targets too —
only their full-attention layers quantize); treat it as a context-length/RAM lever, not a speed lever —
measured at 32k the quantized-KV attention kernel is a little slower than bf16 at the widths that
matter, so leave it off unless RAM is the constraint.
The third thing that grows is RAM: the KV cache is linear in context. Measured on Qwen3.8-27B it costs
0.086 GB per 1k tokens of context (identical for both quants — the cache is bf16 regardless of weight
bits), i.e. ~11 GB on top of the weights at 128k — the "+ cache at 128k ctx" column in the
models table. When RAM is the constraint, cap it with --context-window N (also a per-swap
context_window override on /admin/load): requests past the cap get the "prompt is too long" error that
agent clients like Claude Code auto-compact on, instead of a swap-storm. Since v0.12.3 serve does this
math for you at load — the window defaults to the model's own maximum (262144 on Qwen3.8-27B ≈ 16 GB of
KV on top of ~29 GB of weights), and if weights + full-window KV would overrun your GPU working set it
prints a warning with a --context-window value that fits.
Four drafters from the same DeepSpec lineage, all EAGLE-family (a tiny drafter that consumes the target's hidden states): EAGLE3 is autoregressive (high quality, draft latency grows with block size); DFlash drafts a whole block in one pass (fast, but later positions collide — "suffix decay"); DSpark = DFlash's parallel backbone + a rank-256 Markov head that reinjects token-to-token dependency, fixing suffix decay for ~0.6 ms/round; DFlash 2 (Inco AI, 2026-08) = the DFlash backbone + a candidate path selector + dynamic convolutions — it keeps the target head's top-16 candidates per position and walks one coherent chain through them, fixing the same incoherence with a trained selector instead of a Markov head. This is the first MLX port of DSpark; it also runs z-lab's original DFlash (block diffusion, Chen et al., arXiv:2602.06036, MIT) and the DFlash 2 heads through the same lossless loop.
Current verdict (this M4 Pro, mlx 0.32.1): DFlash 2 wins where its checkpoints exist (Qwen3.8-27B, both quants — the tables above); DSpark wins everywhere else. The mechanism matters more than the scoreboard: DFlash 2's selector buys its acceptance at the same verify width as DSpark's block, so the win survives the M-series rule that killed original DFlash on small targets — acceptance per unit of verify width is the objective, and it is the axis DFlash 2 actually moves.
mlx-version note: the two multi-prompt tables below are the last full sweep, measured on mlx 0.31.2. On mlx 0.32 the balance shifted toward DSpark — narrow multi-row verify got disproportionately cheaper, so on the same code prompt Gemma-12B now measures DSpark cap-2 at 2.11× vs DFlash full-16 at 1.63×, and the 12B "DFlash wins code/math" pick no longer holds on this M4 Pro (the 8B "full block is a net loss" verdict still does: 0.86×). The per-domain acceptance numbers below are mlx-independent and remain the useful part; re-run
mlx-dspark benchmarkfor current throughput on your setup.
Gemma-4 12B (it-8bit, M4 Pro, warm, greedy, 4 prompts/domain — accept / tok·s; greedy ≈ 17.3 tok/s):
| method | chat | code | math |
|---|---|---|---|
| DSpark (cap 2) | 2.45 / 28.5 | 2.78 / 32.8 | 2.86 / 32.4 |
| DFlash (cap 2) | 2.15 / 24.2 | 2.76 / 31.3 | 2.71 / 29.6 |
| DFlash (full 16) | 2.68 / 16.9 | 5.95 / 36.6 | 6.20 / 36.3 |
They're complementary, matching the paper's framing: DFlash's block-16 wins structured content on both axes (accept ~6.0 on code/math vs DSpark's block-7 ceiling ~2.8; ~2.1× throughput) because high acceptance amortizes the wide verify; DSpark's Markov head wins open chat (2.45 / 1.65×; DFlash's block never fills on unpredictable text — full-16 chat is a slight net loss).
But the winner flips on a smaller, cheap-verify target. Qwen3-8B-8bit (warm, greedy, 3 prompts/domain; greedy ≈ 28.8):
| method | chat | code | math |
|---|---|---|---|
| DSpark (cap 2) | 2.38 / 45.7 | 2.55 / 48.8 | 2.40 / 46.1 |
| DFlash (cap 2) | 1.99 / 33.8 | 2.22 / 37.0 | 2.11 / 35.7 |
| DFlash (full 16) | 2.19 / 21.1 | 2.94 / 27.6 | 2.66 / 25.5 |
Here DSpark wins everywhere (~1.6×) and DFlash's block advantage evaporates — full-16 is a net loss
(~0.9×) because the cheap verify makes the wide block cost more than it returns, and accept never climbs
(~2.9 on code vs 5.95 on the 12B). Cross-checked against z-lab's own optimized runner
dflash-mlx on the identical target+drafter: its baseline matches
ours (29.3 tok/s) and its DFlash is also a net loss / wash at 8B (0.92× code full-block, ~1.08× adaptive) —
even with its hand-written Metal verify kernels. So this is DFlash at this model scale on Apple Silicon,
not an artifact of our verify loop.
The MoE target is the sharpest case of that flip yet, and it separates the two axes cleanly. Qwen3.6-35B-A3B-4bit (M4 Pro, warm, 200 tok, median of 3, baseline ≈ 86.0 tok/s) — same target, same tap layers, DSpark's block-8 head (1.53B, standalone) vs z-lab's block-16 head (386M, reusing the target's embed/lm_head):
| method | chat | code | math | mean |
|---|---|---|---|---|
| DSpark (conf 0.3) | 3.12 / 92.0 | 4.02 / 107.8 | 7.03 / 142.1 | 1.33× |
| DFlash (block 8) | 3.77 / 73.5 | 4.39 / 83.8 | 7.48 / 127.6 | 1.11× |
| DFlash (full 16) | 3.52 / 51.6 | 4.17 / 61.3 | 9.62 / 128.5 | 0.94× |
DFlash out-drafts DSpark on every single prompt — 9.62 accepted tokens per round on math is the highest acceptance this project has ever measured — and still loses on throughput, badly. This target has the steepest verify curve here (cost rises from the very first extra row, because each one pulls in a fresh set of routed experts), so a 16-wide verify is ruinous no matter how much of it gets accepted. It is the "cheap-verify target" rule from the 8B row, sharpened: acceptance is not the objective, acceptance per unit of verify width is. Worth knowing before reaching for a bigger block on any future MoE.
Per the paper (accept length, full block, temp=1.0), DSpark beats DeepSpec's DFlash by +16–18% and EAGLE3 by +27–31%; our greedy exact-match numbers are lower than the paper's temp=1.0 speculative-sampling numbers because greedy is the strictest possible accept rule (not a bug).
Since verify dominates, target precision is a speed/quality knob (mlx-0.31.2-era sweep — the 8-bit column is higher on 0.32, see Results at a glance; the qualitative trade-off is unchanged):
| target | 8-bit (default) | 4-bit |
|---|---|---|
| Gemma-4 12B | greedy 17.5 → spec 30 tok/s (1.73×) | greedy 30.6 → spec 34–38 tok/s (1.1–1.25×) |
| Qwen3-4B | greedy 49.8 → spec 73 tok/s (1.45×) | greedy 82 → spec 96–103 tok/s (1.17–1.26×) |
8-bit for the biggest spec benefit + best quality; 4-bit for max absolute throughput or small RAM
(--model …-it-4bit). The drafter stays 4-bit; a bf16 target is not a win (verify roughly doubles).
--max-draft, mlx-dspark benchmarks this pair's verify/drafter cost curves once (~5 s, cached
on disk) and picks the best fixed cap. It has to be measured, because the answer moves a lot — on one
M4 Pro under mlx 0.32 the optimum spans cap 2 to 7, and the same model wants cap 2 at 4-bit, 4 at
8-bit and 6 at bf16. Pass --max-draft N to pin it. --confidence-threshold 0.3 truncates the block
adaptively via the confidence head — it pays exactly where the verify curve still rises inside the
cap's window (Qwen3.8-27B-4bit at cap 7, the MoE), and measures worse where the curve is flat (most
8-bit targets). For Bonsai-27B use --max-draft auto (see its section).quantized_matmul re-pays the whole weight
read per row at verify widths 2–8; a vendored simdgroup_matrix kernel dequantizes each 4/8-bit
weight group once and reuses it across rows, making widths 6–8 cost ~width-5. It is enabled per shape
only after a one-time cached probe proves it faster and numerically sane on your machine
(the wide-GEMM doctrine); everything else stays on the stock kernel. --no-small-m forces it off
for A/B runs — on generate, benchmark and (v0.12.3) serve, where /health reports the live
state (small_m) and /admin/load takes a per-swap small_m boolean. Output stays greedy-correct
(the target verifies every token); ids can differ from the stock kernel at floating-point ties, same
class as the batched path. This is what moved Qwen3.8-27B-8bit's derived cap to 7.--wired-limit — off by default, and you almost certainly want to leave it that way. It raises MLX's
wired-memory ceiling to the recommended working set (~75% of RAM) so weights can't be paged out. Wired
pages can't be reclaimed by the OS, so on a machine already holding a large working set this can hang
macOS hard enough to need a power cycle — and a 16 GB Mac, where "the model nearly fills RAM" is exactly
the situation it was meant to help, is the most likely to wedge. It has also corrupted the verify logits on
the gemma-4/mlx-vlm route (garbage logits can commit wrong tokens, not just crash); mlx-lm targets didn't
reproduce that. It bought no measurable speed where tested (<1%, inside run-to-run noise). Reach for it only
if you actually see paging stalls, and validate a long run before trusting the output.--max-draft auto — measures this machine + model's verify/drafter cost curves once (a few seconds,
cached on disk) and picks the cap per round from the curves + live acceptance and observed round
times, so it tracks the hardware and the mlx version instead of a hard-coded cap=2. It can also
park speculation entirely (plain pipelined steps + periodic probe rounds) on content where
speculation would lose — the safety net that makes it the recommended setting for Bonsai. Lossless —
the cap only sets how many drafts get verified.--no-lookup-drafts
turns it off. --mode lookup runs the same n-gram speculation with no drafter at all, for any target.
Match-scaled long drafts (--lookup-long-draft, default 32): a copy run whose context matches ≥8
tokens deep earns drafts up to ~2× the matched length — verify width 16–32 is a measured plateau on
M-series (~2.5× the cost of one step), so verbatim spans commit ~20–30 tokens per forward. Measured
(8-bit, M4 Pro, outputs bit-identical): gemma-12B file re-emission 3.0×→4.5× (75 tok/s), Ornith-9B
rename-edit 2.8×→3.6× (93 tok/s); chat unchanged. An acceptance gate parks the scaling on
insertion-heavy edits (measured neutral there).--max-draft 0 (full 16-block) is its native point and reaches ~6 accepted tokens on
code/math; on current mlx that still measures below DSpark on this M4 Pro (see
DSpark vs DFlash), so treat DFlash as the head-to-head benchmark
option rather than the speed pick. Short caps on open chat; the full block never fills there.--temperature > 0 (+ --top-p / --top-k) is lossless w.r.t. the target at temperature T
(the paper's §2.1 method). On M-series it's ≈ greedy speed (the extra acceptance lives in a tail a short
cap never reaches) — it's a sampled-output feature, not a speed lever.MIT — see LICENSE. An independent MLX port of the inference path of DeepSeek's DSpark drafter;
the z-lab DFlash drafter classes are vendored (MIT) with attribution in NOTICE. No model weights
are bundled.
Muse-Glimmer-30B — the first muse_glimmer target (Meta: multimodal, DENSE ~30B,
3:1 sliding/full attention, NoPE global layers). Needs mlx-vlm ≥ 0.6.12 and a replicated
hidden-state tap (its language model has no capture hook, unlike gemma4); its community DSpark
drafter (DaoCloud, DFlash-lineage causal SWA) is the first head here to reuse both the
target's embed_tokens and lm_head. That causal block attention also lets the loop truncate
the 15-wide 2.3B-param drafter backbone to the cap rows the head reads — bit-identical, worth
+10–13% end-to-end on this pair (0.8.1). Both tables show the 8-bit target
(mlx-community/Muse-Glimmer-30B-8bit) at cap 4 (auto's pick — its verify curve is flat to
width 5, knees at 6) with lookup drafts off — now this pair's shipped default (registry
row). The hook-table row is the best measured per
content — cap 4, each prompt paired against its own baseline, medians of 3 interleaved
trials; per-content speedup tracks acceptance (math accepts 4.4 on that prompt), so it moves
with content. The Results at a glance row is the fixed benchmark suite,
reproducible with mlx-dspark benchmark; cap 3 is within a few % of cap 4 on chat/code there
(auto-cap adapts per content). 8-bit ~doubles the 4-bit ratio (4-bit: cap 2, accept 2.45,
1.57×/1.70×/1.94× chat/code/math, ~25 tok/s) because it sits nearer the drafter's BF16
training verifier and its verify knee is wider — but 8-bit decode reads ~2× the bytes, so
absolute throughput is ~parity with 4-bit on code and lower on chat: the better ratio buys
8-bit quality at ~4-bit speed, at a peak of ~40 GB RAM (fits 48 GB but tight). The
registry default target is the 4-bit build (~18 GB, smaller Macs); the same drafter
auto-resolves for either quant; bf16 (~60 GB) does not fit 48 GB. Lossless — muse's
output_multiplier 0.196 + logit softcap make fp near-ties more frequent, so it diverges from
sequential greedy at more positions than a typical dense model, every one a sub-ulp tie
(cap 2 and cap 4 diverge at the same position). ↩↩
Qwen3.6-35B-A3B — measured at --confidence-threshold 0.3 (5 trials, median) with
lookup drafts off — the latter is now this pair's shipped default (registry row), the
confidence threshold still needs the flag; its shipped-default cap is 3, worth 1.27×. The only pure-MoE row, and the one where the ratio is the least
interesting number — it is the fastest model in these tables in absolute terms, because only
~3.8B of its 35B parameters are active per token, and that same property is what caps the
ratio (each extra verify row pulls in fresh routed experts). See the MoE discussion under
Results at a glance. ↩
Qwen3.8-27B — two community drafters, one per quant (each matched to the precision
it was trained against), both with the small-M MMA verify kernel on by default (a
one-time probe verifies it; it makes 4-/8-bit verify widths 6–8 cost ~width-5 by
dequantizing each weight group once per row-block instead of per row). 3-trial medians,
hybrid lookup drafts off — this pair's shipped default (the registry rows carry it).
The 4-bit row runs DimInfer/Qwen3.8-27B-Dspark-v1, a DeepSpec-stock Qwen3DSparkModel
(ungated qwen3 backbone, plain rope, block_size 15, tap layers [1,16,31,46,61], reuses
the target's embed and lm_head) trained for the Q4_K_M / 4-bit class: 1.99× mean at a
calibrated cap of 7 (2.31× math / 2.14× code / 1.51× chat, accept 3.28/4.86/5.32), ~29 tok/s
in ~18 GB. It out-accepts the previous 4-bit head (RadixArk, cap7+conf0.3 = 1.82× the same
session) at every cap and content; the confidence head does not pay here (acceptance is
already high, so truncation only sheds accepted tokens) and block-15 buys nothing past cap 7
(verify width 9 exits the kernel window), so --max-draft 7 with no --confidence-threshold
is the recommendation — and static_cap picks 7 unaided, so a no-flag --model already
lands it. The 8-bit row runs RadixArk/Qwen3.8-27B-DSpark, the first
SpecForge/SGLang-packaged head here (DFlash backbone + DeepSpec markov/confidence heads,
YaRN rope, block_7, reuses embed and lm_head; card: accept 3.39 at temp 0.6 vs the FP8
target it was trained against): the kernel removes 8-bit qmm's width-6 cliff so the derived
cap moved 4 → 7 with no flag — 2.72× mean (3.37× math / 2.84× code / 1.95× chat, accept
4.05, math accept 5.15). 8-bit lifts RadixArk's acceptance (2.44 → 3.43)
because it is the matched precision — the Ornith/Qwen3.6-27B pattern again. Lossless both
quants (fp ties only). Since 2026-08-19 the hook-table numbers for both quants come from
the DFlash 2 drafter (incoai/Qwen3.8-27B-DFlash2, one head serves both quants), which
beats both DSpark heads at the identical verify width — same-session head-to-heads and the
lossless/caching notes are under
DFlash 2 on Qwen3.8-27B; the
registry rows carry mode: dflash, so --mode auto (and the Mac app) resolve it, while
the DSpark numbers in this footnote remain that mode's measured best for A/B. ↩↩↩↩↩
Nemotron-3.5-Lightning-30B-A3B — the first Mamba-2 + MoE hybrid target
(nemotron_h, NVIDIA's official DSpark head), the project's first non-attention recurrence,
with an exact Mamba-2 spec rollback. Lookup drafts off everywhere (a net loss on it, as on
every MoE — now this pair's shipped default via its registry row). This model's speedup is unusually content-sensitive, so the
two tables differ more than for other rows. The hook-table row is the best measured per
content at --max-draft 4, each prompt paired against its own baseline: math 1.34×
(accept 4.41, 80 → 108 tok/s, medians of 3 on 0.8.1) and chat 1.07× are 0.8.1 measurements;
code 1.27× is the v0.8.0 stamp (accept 4.55 — 0.8.1's drafter truncation adds +2.5–3% on
byte-identical output, so it stands). The Results at a glance row is
the fixed benchmark suite (re-stamped on 0.8.1), where acceptance is lower (~3.3) and
cap 3 beats cap 4 — suite chat at cap 4 is a slight net loss (0.83×), which is why
auto-cap's pick of 3 is the right default there. Like the other MoE, the ratio is bounded by
the verify-width cost of routed experts, not the drafter. ↩
Community-drafter rows. Qwen3.6-27B runs the 8-bit target with
satgeze/Qwen3.6-27B-DSpark — a block-15 head (vs 7 everywhere else) trained against the
bf16 target with DeepSpec's online mode and warm-started from z-lab's DFlash head for the
same target. Rule of thumb: match the target's precision to what the drafter was trained
against — Ornith's drafter (bf16-qualified) wants 8-bit, and so does this one.
Qwen3.8-27B runs two heads (see the 3 footnote): the 4-bit target uses
DimInfer/Qwen3.8-27B-Dspark-v1 (a 4-bit-class DeepSpec head, block-15, out-accepts the
alternative at 4-bit), the 8-bit target uses RadixArk/Qwen3.8-27B-DSpark, the first
SpecForge/SGLang-packaged head here — matched to the FP8 verifier it was trained against.
Ornith-1.0-9B (an agentic-coding qwen3_5 hybrid, drafter qualified against the bf16 verifier)
runs the 8-bit house sweet spot — the first target here with chat above 2× — and its
acceptance is so high on code (p≈0.96/position) that auto-cap drives the cap to the full
block of 7. The 4-bit Ornith target trades the ratio for absolute speed: ~1.4–1.55× but
60–76 tok/s (baseline 49.3) — pick 4-bit for peak tok/s, 8-bit for quality and the headline
ratio; the same drafter auto-resolves for both. And don't bother with a bf16 target for
speculation: we swept it (Ornith bf16: 1.54× code at cap 3, 22.9 tok/s) — the ratio is
non-monotone in bits and peaks at 8-bit, because MLX's unquantized matmul pays a ~2× cost
cliff at verify width 2 where the quantized kernels stay flat. bf16 is slower than 8-bit in
both ratio and absolute speed here. ↩↩↩↩↩
Qwen3.6-27B is measured on the 8-bit target; the 4-bit target resolves the same drafter but is not measured. ↩
Qwen3-14B is not in the auto-resolve registry — pass
--drafter deepseek-ai/dspark_qwen3_14b_block7. ↩